Apple silicon
Apple Mac Studio (M5 Max)
- Memory
- 128 GB
- Bandwidth
- 614 GB/s
Largest popular model at 4-bit: Qwen3.5 122B A10B
128 GB at 614 GB/s: gpt-oss-120b and 122B MoE models at a good pace, almost silently.
Every graphics card, Mac, mini PC and edge board worth considering for running language models locally, with memory, bandwidth, software support and prices.
33 platforms
Apple silicon
Largest popular model at 4-bit: Qwen3.5 122B A10B
128 GB at 614 GB/s: gpt-oss-120b and 122B MoE models at a good pace, almost silently.

NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
The fastest consumer card for local AI: 32 GB and 1.8 TB/s make 30B-class models fly.
Apple silicon
Largest popular model at 4-bit: Qwen3.5 397B A17B
Up to 512 GB at 1.2 TB/s: the only single box that holds DeepSeek R1 or Qwen3.5 397B at 4-bit.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.5 122B A10B
96 GB on one card at RTX 5090 speed: gpt-oss-120b and 122B MoE models entirely in GPU memory.
Ryzen AI
Largest popular model at 4-bit: Qwen3.5 122B A10B
128 GB of unified memory in a mini PC for less than a Mac Studio: the homelab favourite for MoE models.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
The homelab classic: 24 GB and 936 GB/s, bought used. Two of them make 48 GB.

DGX Spark / GB10
Largest popular model at 4-bit: Qwen3.5 122B A10B
128 GB with CUDA in a tiny box: the NVIDIA answer to Strix Halo and the Mac.
AMD GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
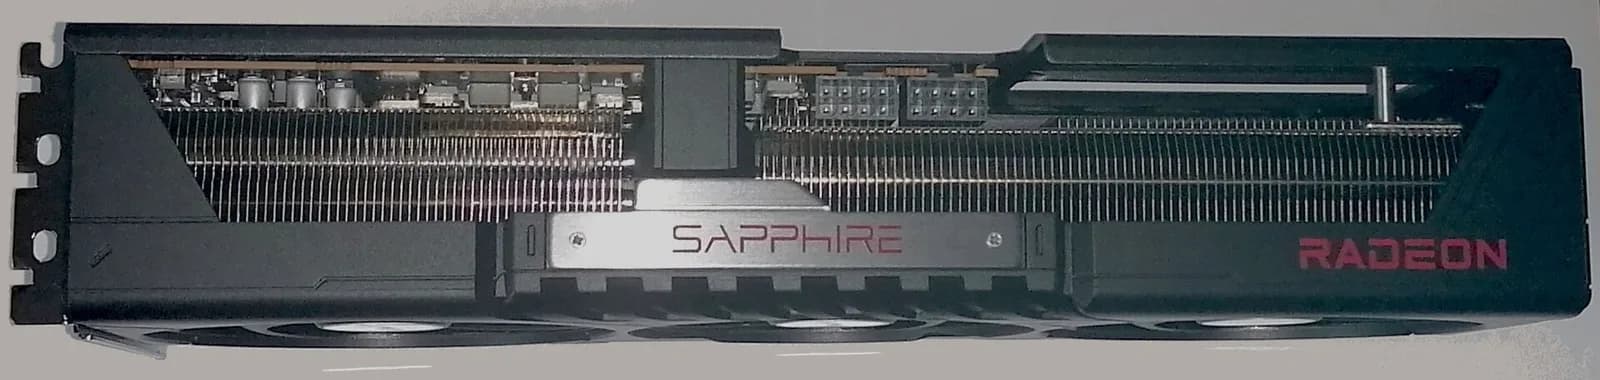
32 GB for about a third of an RTX 5090: the cheapest new 32 GB card.

NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
The cheapest new NVIDIA card with 16 GB. Low power and CUDA make it the easy starter card.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
48 GB in a 300 W blower card: 70B dense models on one quiet-ish GPU.
Apple silicon
Largest popular model at 4-bit: Qwen3.6 35B A3B
Up to 64 GB at 307 GB/s in a quiet mini PC: 27–35B models at a comfortable pace.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
24 GB in a single-slot, 140 W card: the homelab-friendly way to get 24 GB new.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
32 GB at only 200 W: RTX 5090 capacity with half the heat.

AMD GPUs
Largest popular model at 4-bit: Qwen3.6 27B
24 GB and 960 GB/s: RTX 3090-class memory, bought new.
Ryzen AI
Largest popular model at 4-bit: Qwen3.5 122B A10B
Strix Halo's successor with up to 192 GB (160 GB for the GPU): Qwen3 235B in a mini PC.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
Out of production but still a top AI card: 24 GB at 1 TB/s.
Intel GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
Intel's big Battlemage: 32 GB and 608 GB/s for less than AMD's R9700.
NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
Nearly RTX 5080 bandwidth for less. Still 16 GB, so speed rather than size.

AMD GPUs
Largest popular model at 4-bit: gpt-oss-20b
AMD's best gaming card is a solid 16 GB AI card too, with ROCm and Vulkan.
AMD GPUs
Largest popular model at 4-bit: gpt-oss-20b
The cheapest new 16 GB card. Slow memory, but it holds what an RTX 5060 Ti holds.
Intel GPUs
Largest popular model at 4-bit: Qwen3.6 27B
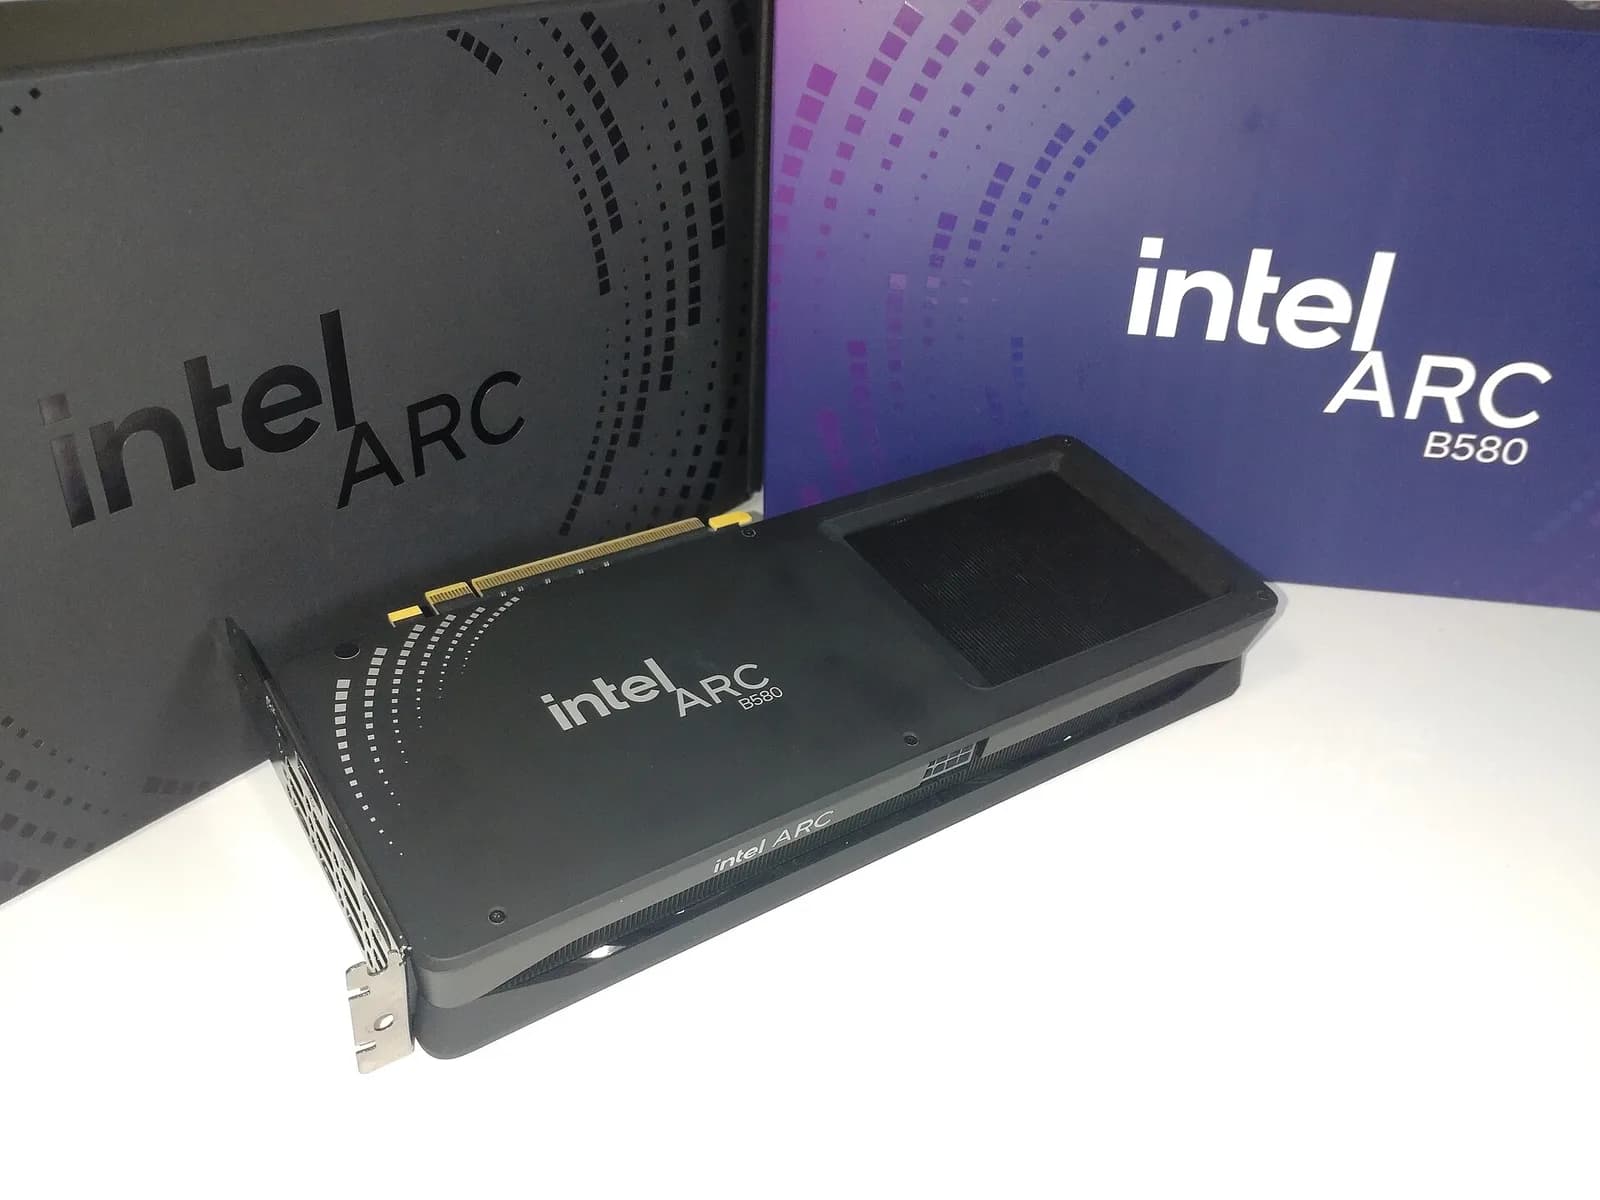
The cheapest new 24 GB card, if you can live with Intel's software.
Edge AI
Largest popular model at 4-bit: Qwen3.5 122B A10B
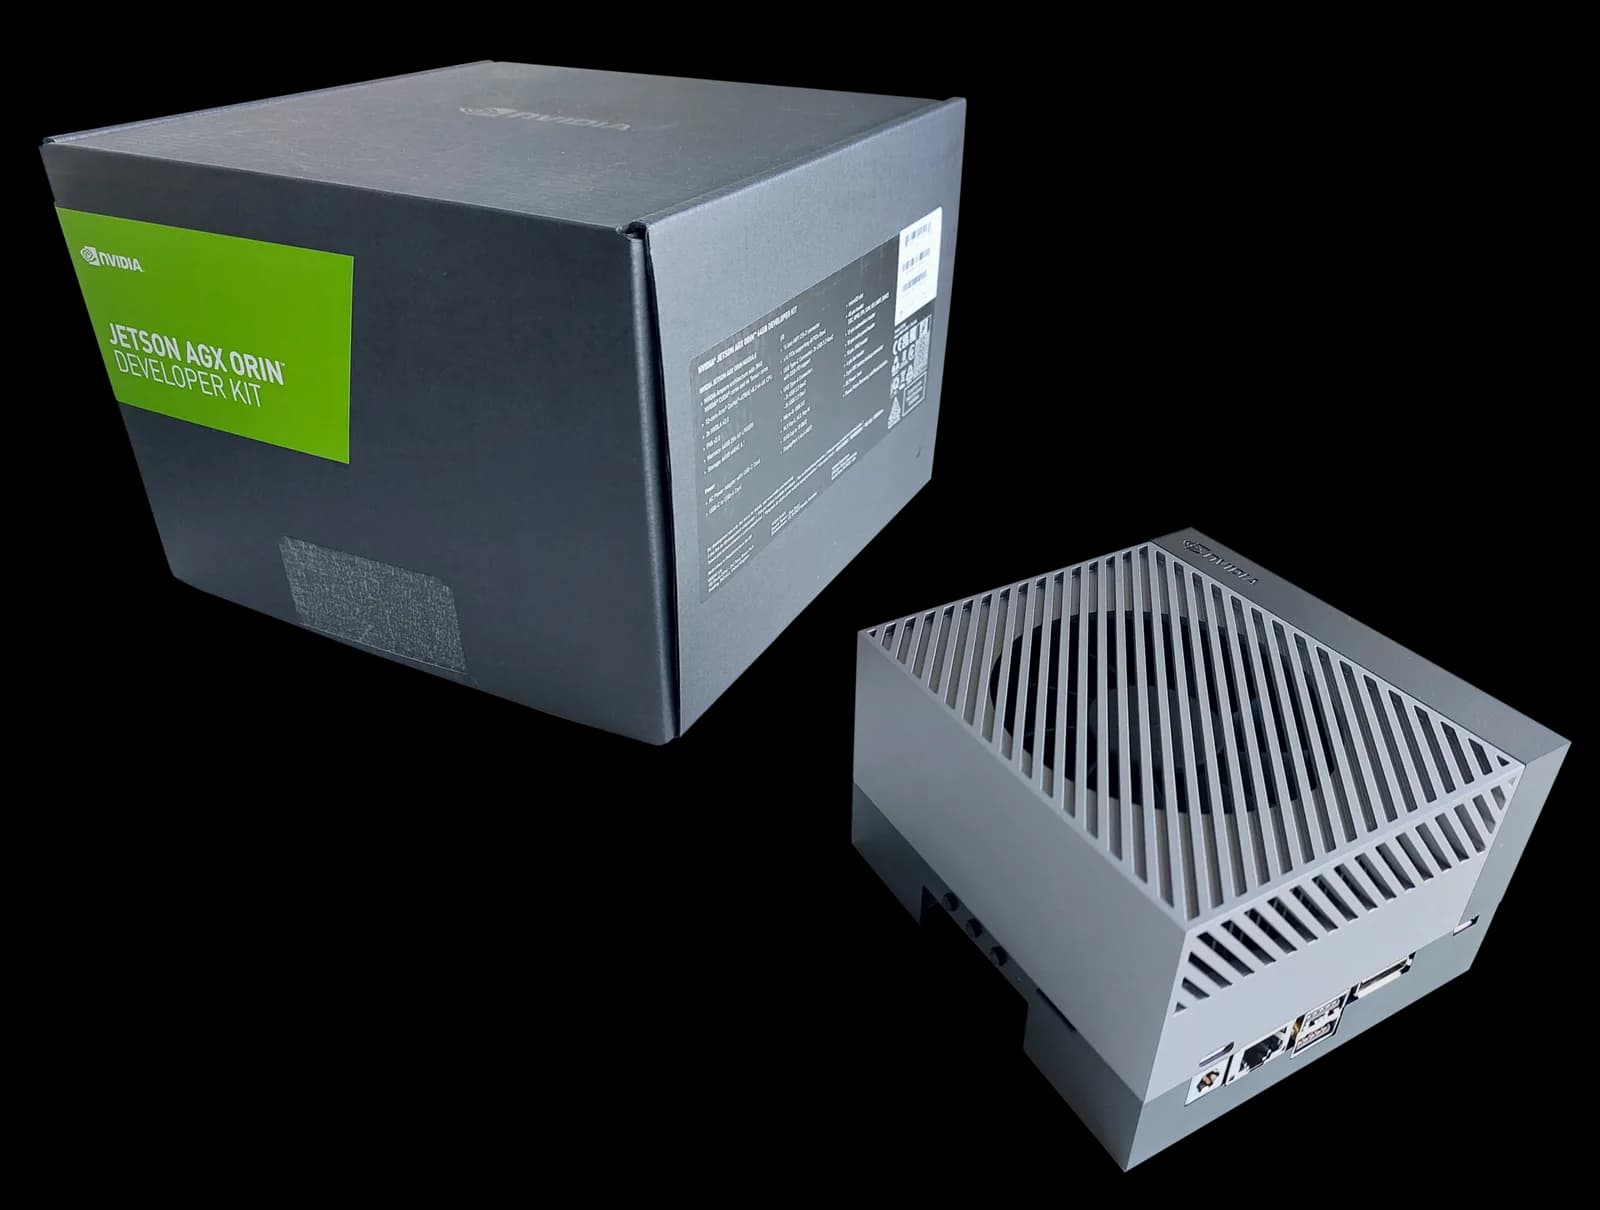
Robotics computer with 128 GB and Blackwell. Similar LLM speed to a DGX Spark.
Apple silicon
Largest popular model at 4-bit: Qwen3.6 27B
A silent, tiny always-on box for small models. Choose 32 GB if AI is the goal.

NVIDIA GPUs
Largest popular model at 4-bit: Gemma 4 12B
The cheapest way into CUDA with 12 GB. Slow, but enough for 7–12B models.
Intel GPUs
Largest popular model at 4-bit: gpt-oss-20b
16 GB in a 70 W, low-profile card with no power cable: made for small servers.
Edge AI
Largest popular model at 4-bit: None of our popular models
A 25 W CUDA board that runs 1–4B models: robotics and smart-home projects, not chat at scale.

Intel GPUs
Largest popular model at 4-bit: Gemma 4 12B
12 GB with decent bandwidth for little money; software is the catch.
Ryzen AI
Largest popular model at 4-bit: Qwen3.5 122B A10B
The mid-range Ryzen AI mini PCs and NAS: up to 96 GB of ordinary DDR5, fine for 8–30B models and small mixture-of-experts models, slow for big dense ones.
NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
Fast, but only 16 GB: the same memory as cards that cost a third as much.

Edge AI
Largest popular model at 4-bit: Llama 3.3 70B
64 GB at 60 W with CUDA. Now outclassed for LLMs by Strix Halo and the Mac mini.
Edge AI
Largest popular model at 4-bit: Qwen3 1.7B
An NPU with its own 8 GB for the Raspberry Pi 5. It runs only Hailo's compiled models, up to about 2B.
NVIDIA GPUs
Largest popular model at 4-bit: Gemma 4 12B
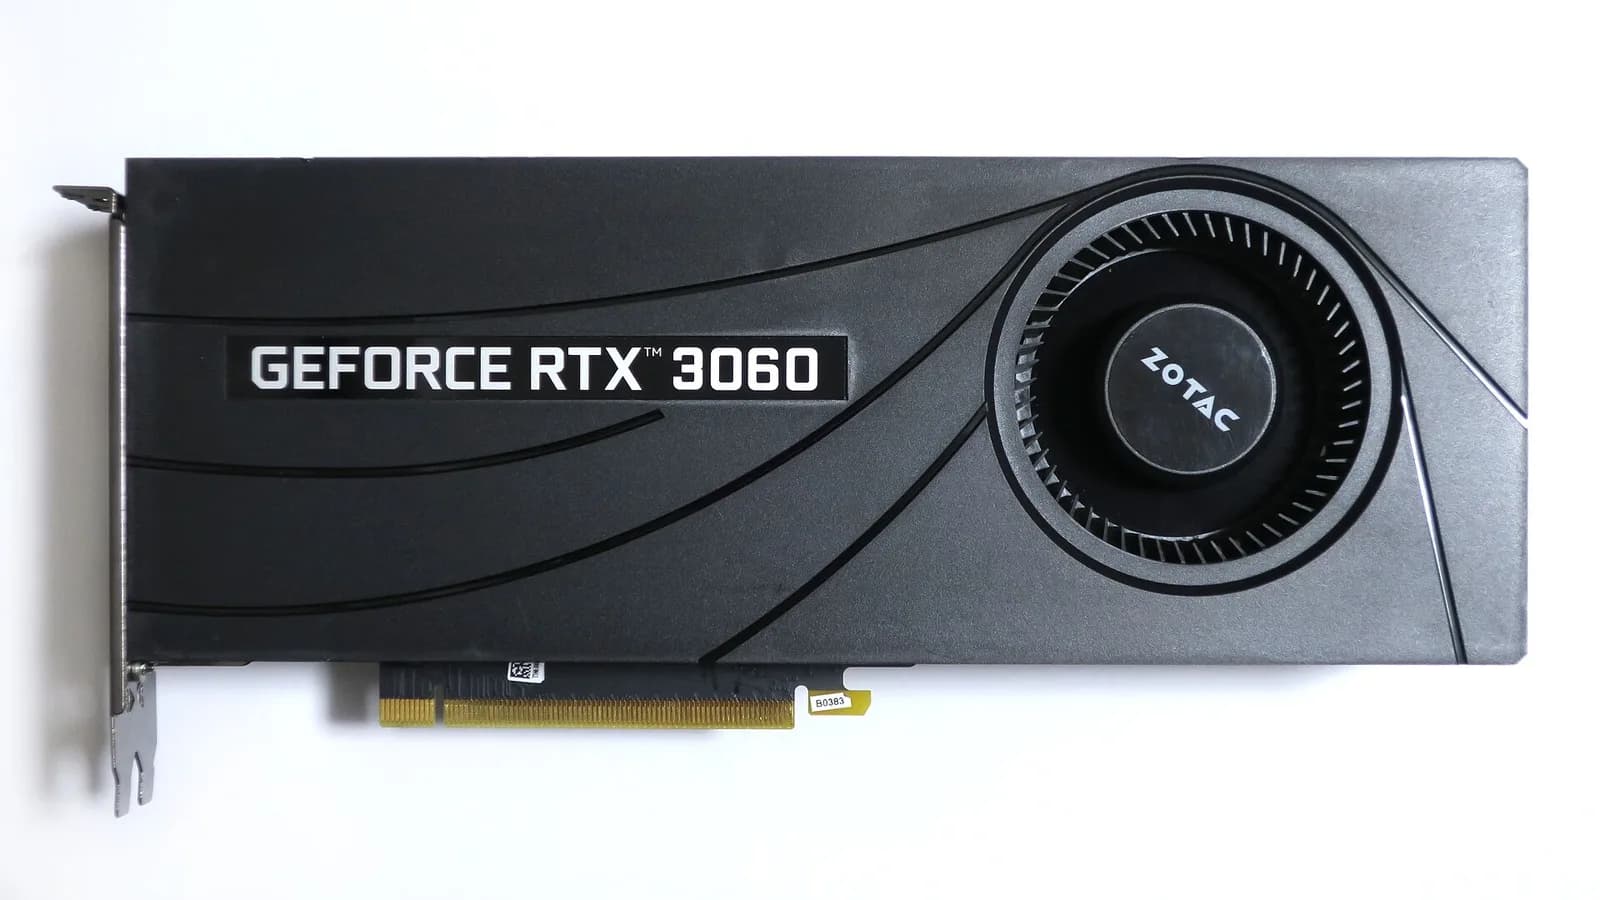
A gaming card with only 12 GB. For AI the 16 GB RTX 5060 Ti is the better buy.
Edge AI
Largest popular model at 4-bit: Qwen3.5 9B
Cheap Arm boards whose small NPU runs converted models through RKLLM. Slow, but very frugal.