NVIDIA GPUs
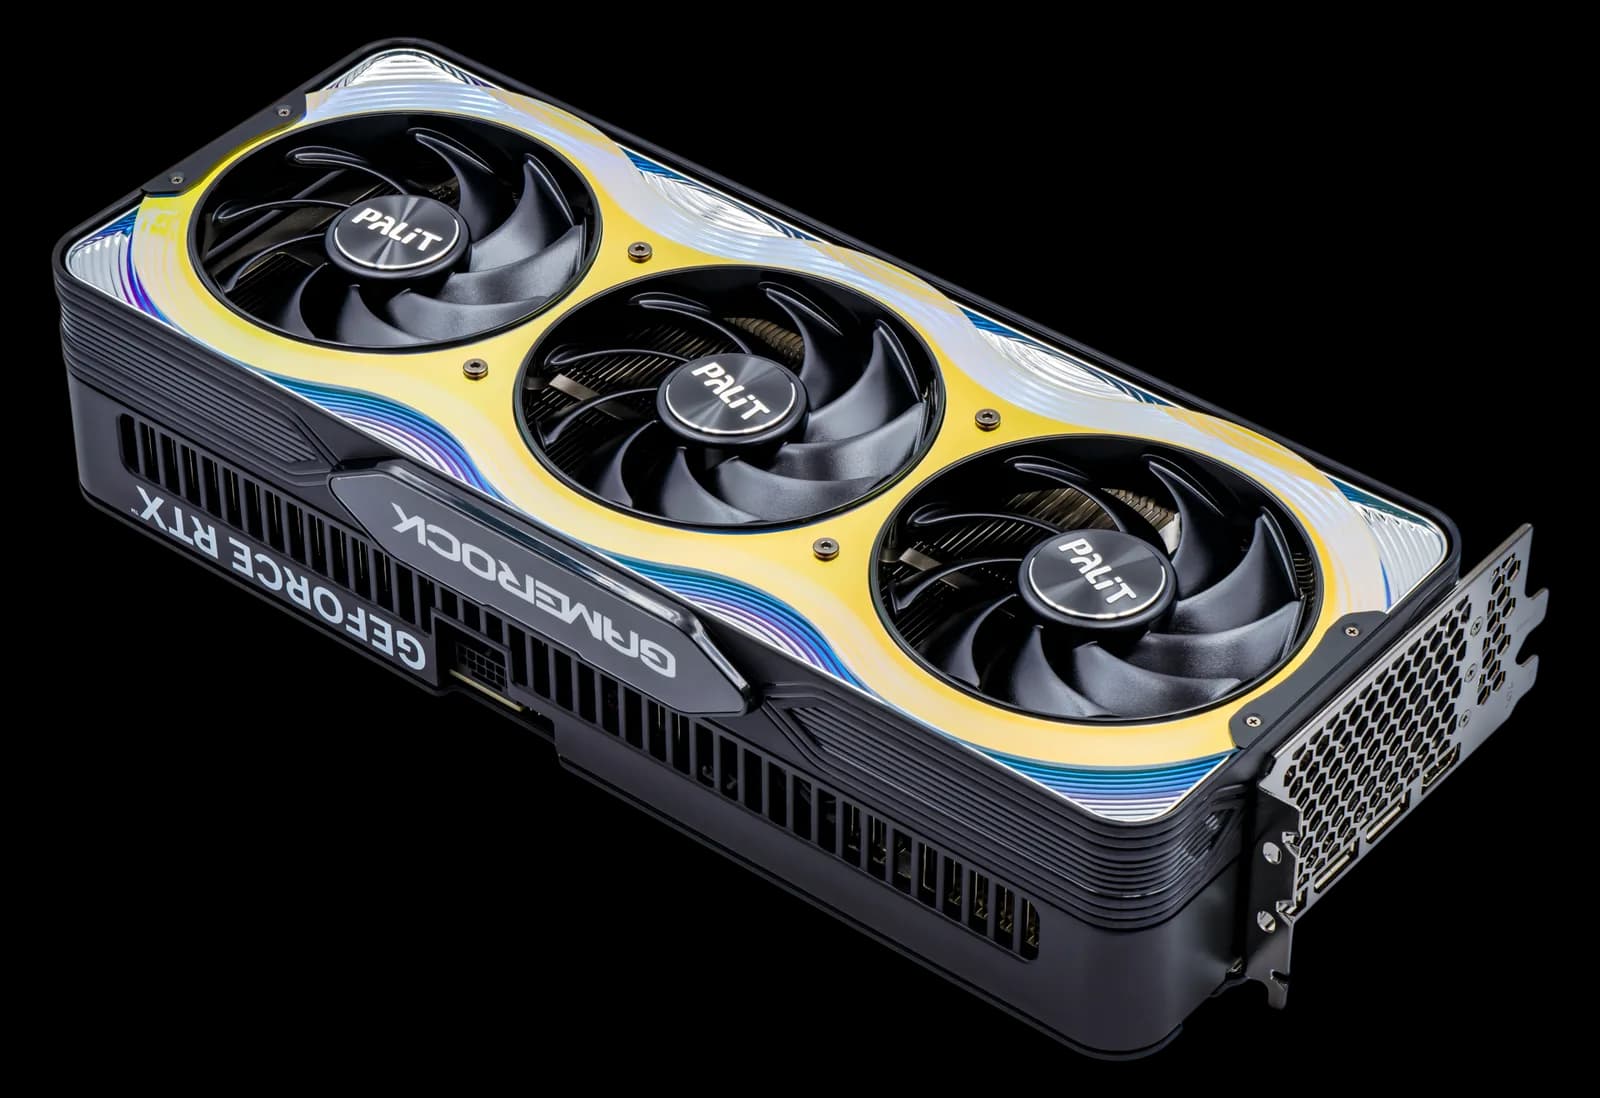
NVIDIA GeForce RTX 5090
- Memory
- 32 GB
- Bandwidth
- 1.79 TB/s
Largest popular model at 4-bit: Qwen3.6 35B A3B
The fastest consumer card for local AI: 32 GB and 1.8 TB/s make 30B-class models fly.
from $4,329 (typical price)Recommended
| In this family | Memory | Bandwidth | Largest popular model at 4-bit | Price |
|---|---|---|---|---|
| RTX 5090 | 32 GB | 1.79 TB/s | Qwen3.6 35B A3B | $4,329 |
| RTX PRO 6000 | 96 GB | 1.79 TB/s | Qwen3.5 122B A10B | $8,565 |
| RTX 3090 | 24 GB | 936 GB/s | Qwen3.6 27B | $1,340 |
| RTX PRO 5000 | 48 GB | 1.34 TB/s | Qwen3.6 35B A3B | $4,500 |
| RTX 5060 Ti 16 GB | 16 GB | 448 GB/s | gpt-oss-20b | $789 |
| RTX PRO 4000 | 24 GB | 672 GB/s | Qwen3.6 27B | $1,500 |
| RTX PRO 4500 | 32 GB | 896 GB/s | Qwen3.6 35B A3B | $2,500 |
| RTX 4090 | 24 GB | 1.01 TB/s | Qwen3.6 27B | $1,599 |
| RTX 5070 Ti | 16 GB | 896 GB/s | gpt-oss-20b | $1,190 |
| RTX 3060 12 GB | 12 GB | 360 GB/s | Gemma 4 12B | $329 |
| RTX 5080 | 16 GB | 960 GB/s | gpt-oss-20b | $1,830 |
| RTX 5070 | 12 GB | 672 GB/s | Gemma 4 12B | $1,010 |
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
The fastest consumer card for local AI: 32 GB and 1.8 TB/s make 30B-class models fly.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.5 122B A10B
96 GB on one card at RTX 5090 speed: gpt-oss-120b and 122B MoE models entirely in GPU memory.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
The homelab classic: 24 GB and 936 GB/s, bought used. Two of them make 48 GB.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
48 GB in a 300 W blower card: 70B dense models on one quiet-ish GPU.
NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
The cheapest new NVIDIA card with 16 GB. Low power and CUDA make it the easy starter card.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
24 GB in a single-slot, 140 W card: the homelab-friendly way to get 24 GB new.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 35B A3B
32 GB at only 200 W: RTX 5090 capacity with half the heat.
NVIDIA GPUs
Largest popular model at 4-bit: Qwen3.6 27B
Out of production but still a top AI card: 24 GB at 1 TB/s.
NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
Nearly RTX 5080 bandwidth for less. Still 16 GB, so speed rather than size.
NVIDIA GPUs
Largest popular model at 4-bit: Gemma 4 12B
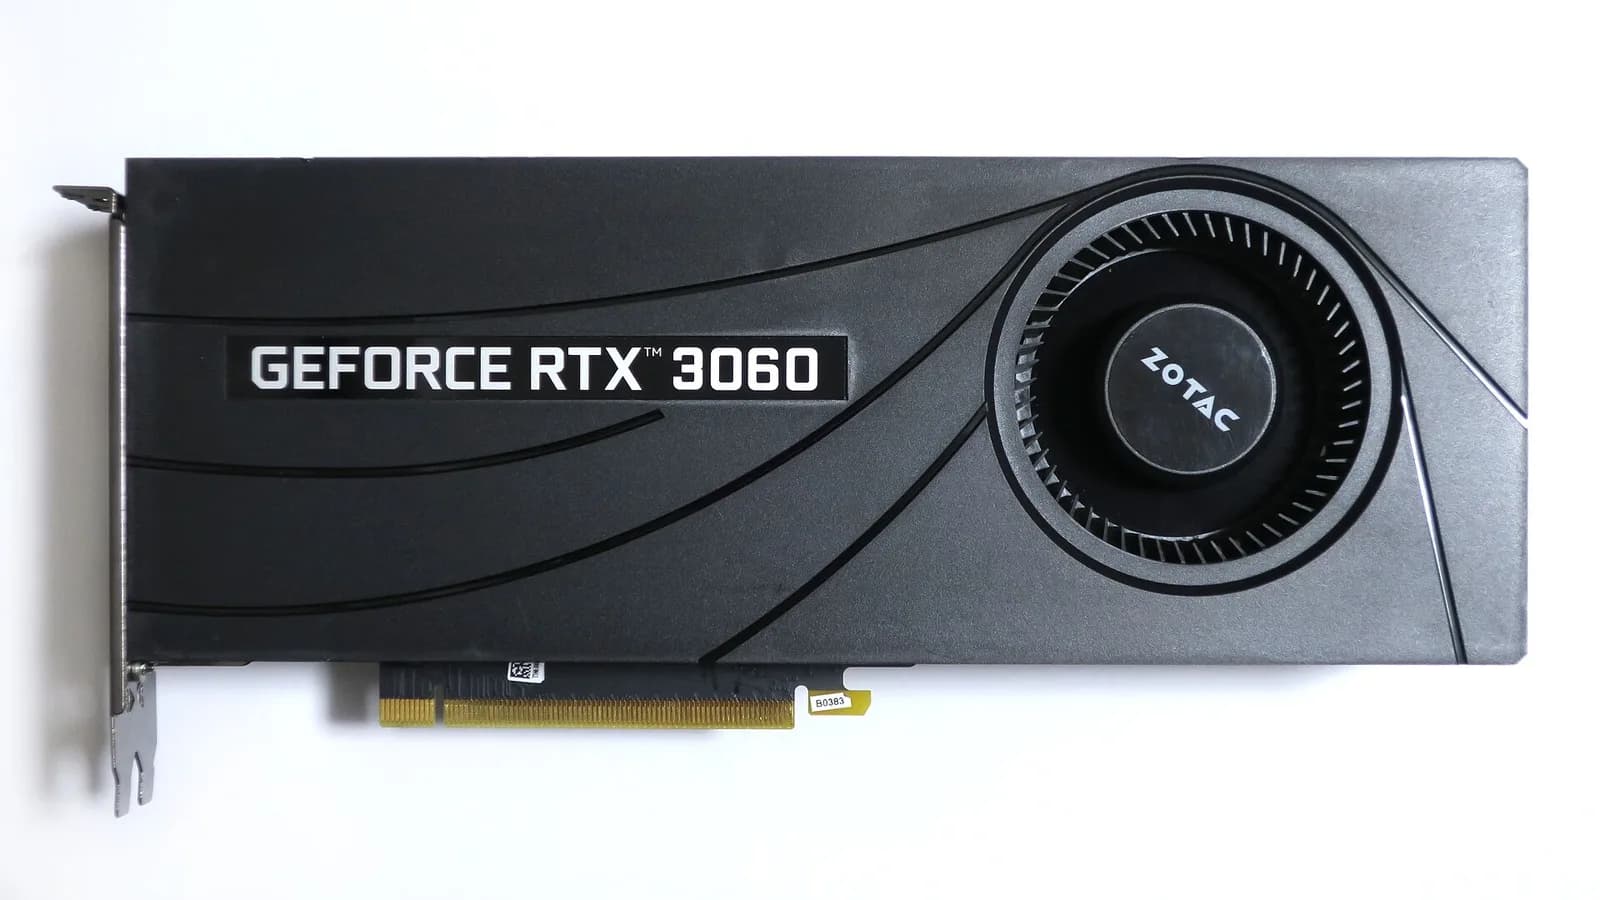
The cheapest way into CUDA with 12 GB. Slow, but enough for 7–12B models.
NVIDIA GPUs
Largest popular model at 4-bit: gpt-oss-20b
Fast, but only 16 GB: the same memory as cards that cost a third as much.
NVIDIA GPUs
Largest popular model at 4-bit: Gemma 4 12B
A gaming card with only 12 GB. For AI the 16 GB RTX 5060 Ti is the better buy.