DGX Spark / GB10 vs Ryzen AI Max+ 395
Recommended
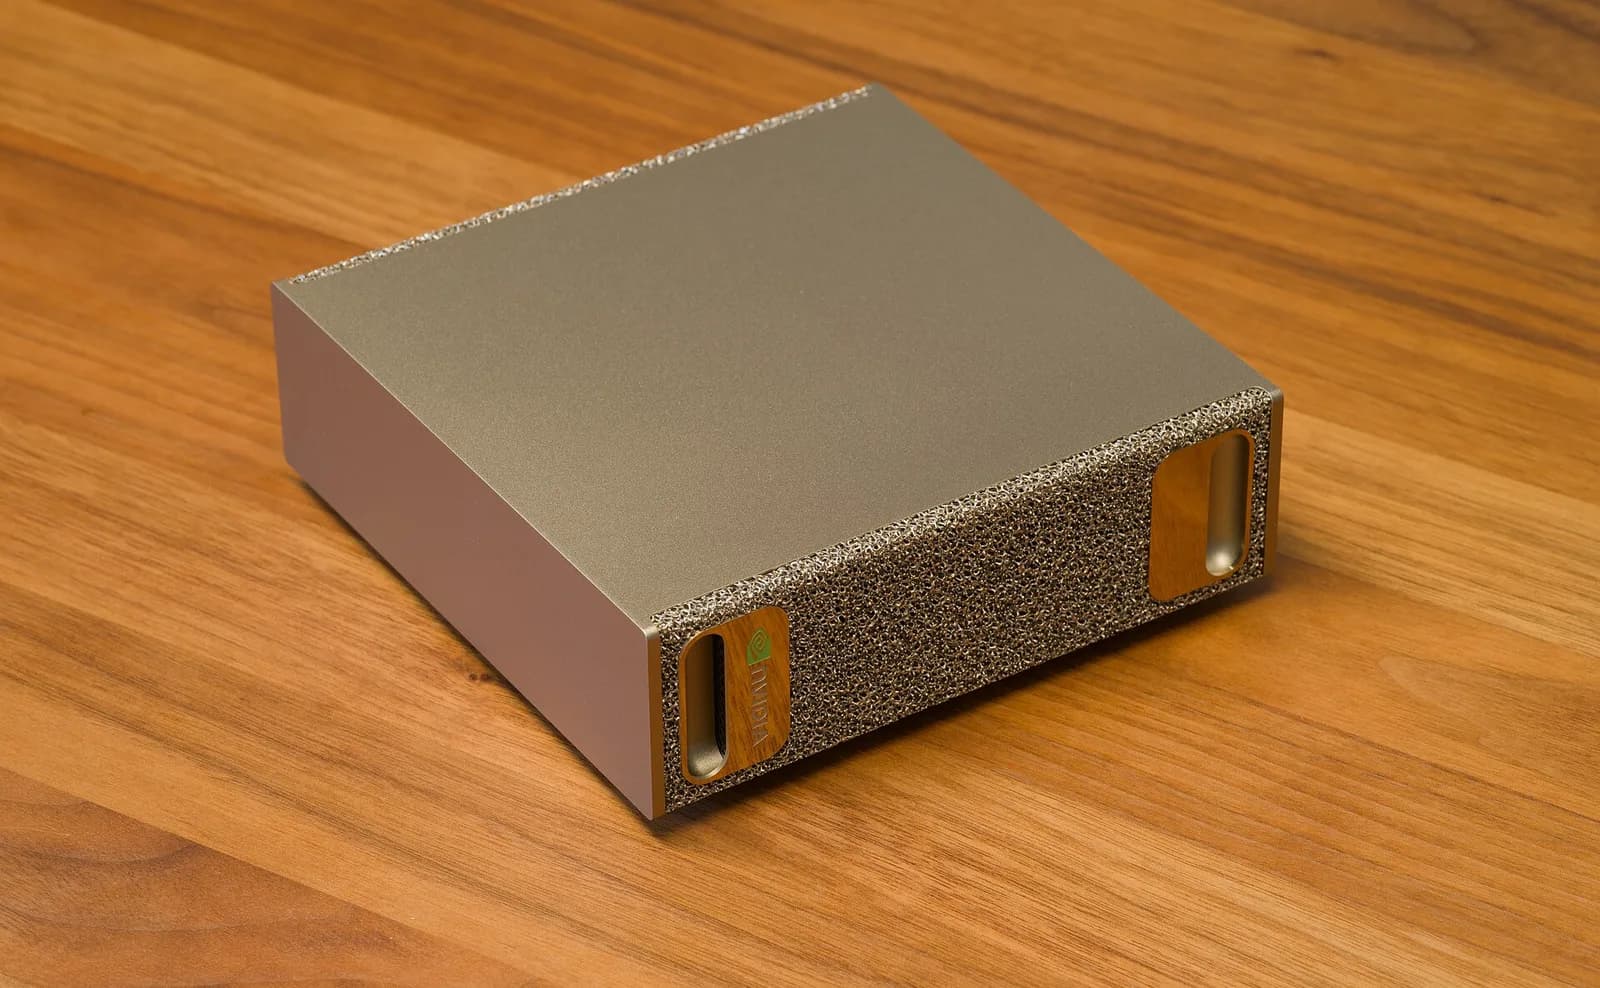
Photo: Daniel Lu (User:dllu) · CC BY-SA 4.0

Illustration
Highly recommended
Our verdict
Editorial opinionOur verdict
Same memory (128 GB) and nearly the same bandwidth (273 vs 256 GB/s), so token generation is similar. The GB10 wins on software (CUDA, vLLM, fine-tuning) and prompt processing; Strix Halo wins on price and is a normal x86 PC. For chat and agents at home, Strix Halo is better value; for CUDA development, GB10.
| Factual data | DGX Spark / GB10 | Ryzen AI Max+ 395 |
|---|---|---|
| Memory (largest) | 128 GB | 128 GB |
| Usable for models | 115 GB | 115 GB |
| Bandwidth | 273 GB/sMore | 256 GB/s |
| Largest popular model at 4-bit | Qwen3.5 122B A10B | Qwen3.5 122B A10B |
| Price from | $5,000 | $2,200Advantage |
| Price per GB | $39 | $19Advantage |
| Power | 240 W | 120 W |
| Compute stack | CUDA (Arm) | ROCm / Vulkan |
Which models each one runs
Popular models at Q4_K_M with a 32K-token context. Memory needed from real model files; speed is the theoretical ceiling.
| Model | DGX Spark / GB10 | Ryzen AI Max+ 395 |
|---|---|---|
| Qwen3 1.7B | Runs≤ 246 tok/s | Runs≤ 231 tok/s |
| Qwen3.5 9B | Runs≤ 48 tok/s | Runs≤ 45 tok/s |
| Gemma 4 12B | Runs≤ 38 tok/s | Runs≤ 36 tok/s |
| gpt-oss-20b | Runs≤ 136 tok/s | Runs≤ 128 tok/s |
| Qwen3.6 27B | Runs≤ 16 tok/s | Runs≤ 15 tok/s |
| Qwen3.6 35B A3B | Runs≤ 148 tok/s | Runs≤ 139 tok/s |
| Llama 3.3 70B | Runs≤ 6 tok/s | Runs, tight≤ 6 tok/s |
| gpt-oss-120b | Runs≤ 100 tok/s | Runs≤ 93 tok/s |
| Qwen3.5 122B A10B | Runs≤ 45 tok/s | Runs≤ 42 tok/s |
| Qwen3.5 397B A17B | Not enough memory | Not enough memory |
Speed ceilings are theoretical; see each page for measured results.