Best hardware to run gpt-oss-120b locally
gpt-oss-120b needs about 65 GB with a 32K context. These are the machines that hold it, from cheapest to fastest.
Editorial opinionReviewed Oct 11, 2026
OpenAI's open model ships with its experts in 4-bit, so it needs about 63 GB of weights in any quantisation, plus a small context cache. Only 5.1B parameters work per token, which makes it fast even on unified-memory machines. Anything with 96–128 GB of usable memory runs it well. See gpt-oss-120b for every option.
- Illustration
#1 · Best value
AMD Ryzen AI Max+ 395 (Strix Halo)
Highly recommended- Memory
- 128 GB
- Bandwidth
- 256 GB/s
- Power
- 120 W
- Largest popular model at 4-bit
- Qwen3.5 122B A10B
from $2,200 (typical price)
Editorial opinionOverall 8.3/10128 GB in an x86 mini PC: the cheapest way to run it comfortably.
- Illustration
#2 · Best overall
Apple Mac Studio (M5 Max)
Highly recommended- Memory
- 128 GB
- Bandwidth
- 614 GB/s
- Power
- 480 W
- Largest popular model at 4-bit
- Qwen3.5 122B A10B
from $2,499 (launch price)
Editorial opinionOverall 8.7/10614 GB/s makes it noticeably faster, and it is silent.
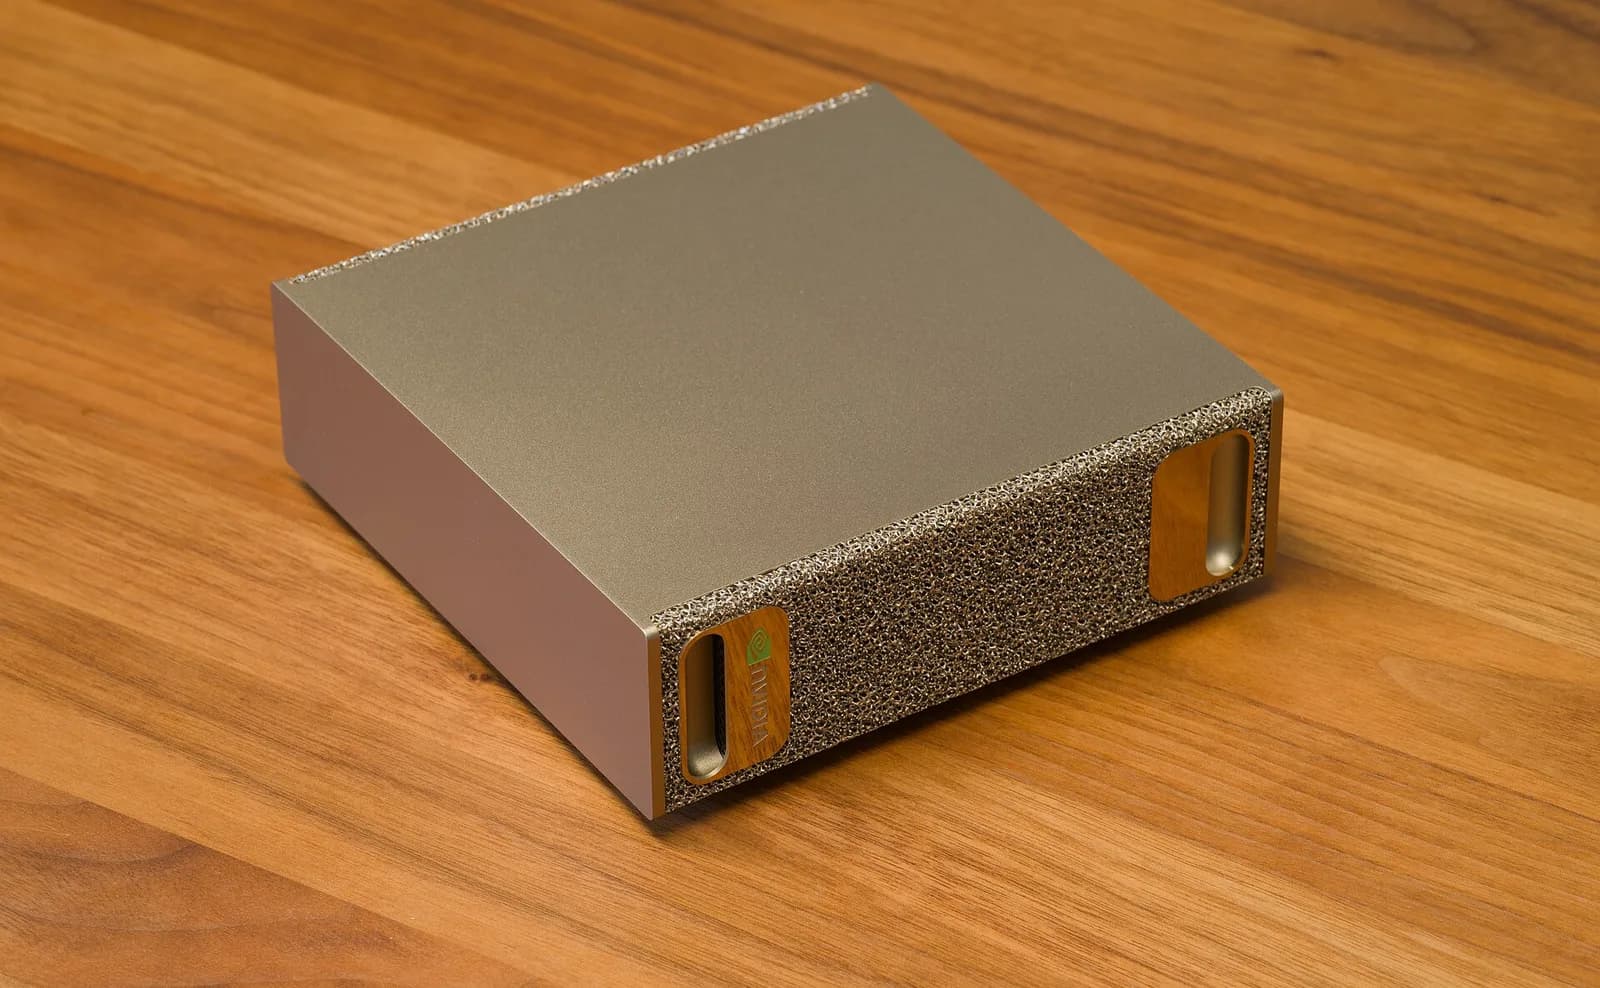
Photo: Daniel Lu (User:dllu) · CC BY-SA 4.0
#3 · Best with CUDA
NVIDIA GB10 Grace Blackwell (DGX Spark and partners)
Recommended- Memory
- 128 GB
- Bandwidth
- 273 GB/s
- Power
- 240 W
- Largest popular model at 4-bit
- Qwen3.5 122B A10B
from $5,000 (typical price)
Editorial opinionOverall 7.6/10Same capacity class with the full NVIDIA stack.
- Illustration
#4 · Fastest
NVIDIA RTX PRO 6000 Blackwell
For advanced users- Memory
- 96 GB
- Bandwidth
- 1.79 TB/s
- Power
- 600 W
- Largest popular model at 4-bit
- Qwen3.5 122B A10B
from $8,565 (typical price)
Editorial opinionOverall 8.4/10Fits entirely in 96 GB of GPU memory at 1.8 TB/s.

How we chose
- Must hold the model with a 32K context in the memory the GPU can use by default.
- Ordered by our overall assessment, weighing price, speed and ease of setup.